Python
Each kind's functions, stream_create, stream_connect, broadcast_create, broadcast_join, queue_create, queue_join, service_create and service_join, and four classes, Listener, Conn, Queue and Service, over the C API through CFFI's ABI mode: the native library is loaded at run time, so there is nothing to compile. A call that doesn't return OK raises FipcError. The wheels carry the library for Windows x64, Linux x64 and ARM64 (glibc 2.34+) and macOS 14.4+ on Apple Silicon; one wheel per platform fits every Python 3.9+.
pip install fipc-pythonServer and client
two processes, one nameStart the two in either order, in two terminals: stream_connect waits up to its timeout for a server to create the stream and accept. stream_create returns a Listener, and the connections are Conns; both are context managers. The pair makes the exchange every example on this site makes, the message ping, answered in upper case: this client works with any language's server, and this server with any language's client (every pair of languages is tested).
import fipc

# rings of 1 MiB each way
with fipc.stream_create("my_channel", 1 << 20) as listener:
    with listener.accept() as conn:  # waits for a client
        message = conn.recv()
conn.send(message.upper())import fipc
with fipc.stream_connect("my_channel", timeout_ms=5000) as conn:
conn.send(b"ping")
print(conn.recv()) # b'PING'IPC overhead
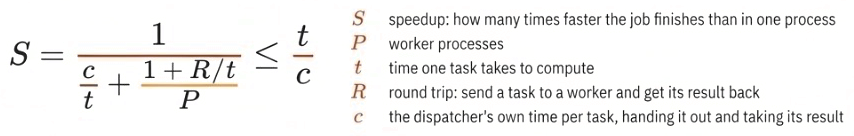
what it costs to hand work to other processes, measuredWorker processes speed a job up only if talking to them is cheap. Every task crosses between processes twice, and that communication overhead, not the work, sets the limit. With one dispatcher handing out tasks of time t to P workers:
- S
- speedup: how many times faster the job finishes than in one process
- P
- worker processes
- t
- time one task takes to compute
- R
- round trip: send a task to a worker and get its result back
- c
- the dispatcher's own time per task, handing it out and taking its result
However many workers, the job runs at most t / c times as fast. Python's own channels cost 20 to 70 µs a round trip and 8 to 56 µs of the dispatcher's time a task: tasks of 20 µs gain nothing from a pool fed through multiprocessing.Queue. FastIPC's round trip, Python to Python, is about 2 µs, so tasks of tens of microseconds scale across the cores. Every point on the chart is measured.
| Transport | Round trip R | Dispatcher c | Ceiling t / c | Best measured |
|---|
Where the formula comes from. Amdahl's law: if a share s of the work must run in one place, P workers finish it at most 1 / (s + (1 − s) / P) times as fast. Handing tasks to worker processes creates such a share even when the work itself splits perfectly: only the dispatcher can send a task and take its result, so its c per task acts as the serial share c/t, and a worker waits a round trip R for every task, which stretches each task to t + R. However many workers there are, the job never runs more than t / c times as fast.
One dispatcher process gives each worker one task at a time and takes the results in turn; each task and result is 64 bytes. R is the round trip with one worker; c the dispatcher's time per task with 2 to 12 workers, the tasks doing no work. Each point is the median of 3 runs.
Messages
bytes of any size, no headerA connection carries messages: send takes bytes of any size, and recv returns each message whole. This server echoes every message back until its client leaves, which ends its next recv with DISCONNECTED.
import fipc

# rings of 1 MiB each way: a power of two, 1 KiB to 2 GiB
with fipc.stream_create("demo", 1 << 20) as listener:
    with listener.accept() as conn:
        try:
            while True:
                msg = conn.recv()     # bytes, any size
                conn.send(msg)        # echo it back
        except fipc.FipcError as e:
            if e.result != fipc.Result.DISCONNECTED:
                raise
print("client gone")import fipc
with fipc.stream_connect("demo", timeout_ms=5000) as conn:
for word in (b"hello", b"shared", b"memory"):
conn.send(word)
print(conn.recv())Errors and timeouts
FipcError.result is a ResultEvery waiting call takes timeout_ms: NO_WAIT (0) doesn't wait, FOREVER (−1, the default) waits for ever. Any result other than OK raises FipcError, whose result says which: TIMEOUT, DISCONNECTED, CANCELLED, TOO_LARGE, INVALID, NO_MEMORY or ADDR_IN_USE, and on a broadcast OVERRUN (the error's lost: how many messages a lossy subscriber lost) or UNSUBSCRIBED, and on a service ABANDONED (the request's server ended before it replied).
DISCONNECTED is final for that connection: close it, then accept or connect a new one.
from fipc import FipcError, Result

try:
    msg = conn.recv(timeout_ms=100)
except FipcError as e:
    if e.result == Result.TIMEOUT:
        msg = None            # nothing yet
    else:
        raise
Zero-copy
up to conn.max_piece() bytesWrite into a memoryview of the ring and commit; read a read-only memoryview of the ring and release it. A view stays valid until its release, the next receive, or close, and keeps its Conn referenced: the garbage collector never closes a connection under a view.
buf = conn.send_acquire(5)    # writable memoryview
buf[:] = b"hello"
conn.send_commit(5)view = conn.recv_acquire() # read-only memoryview
handle(view)
conn.recv_release() # frees its roomBatches
many messages per call, both endssend_many(messages) sends a list of messages in order and publishes them together, with at most one wake of the receivers, and returns how many went; the timeout bounds the whole call (NO_WAIT: only what fits now). Every message is checked before any goes. An error is the first message that didn't go, and the error's sent says how many did.
recv_many(max_count) waits for the next message, then takes every further one already there (up to max_count, as many as fit the connection's buffer) and returns them as a list of bytes. A broadcast's subscriber takes those its publisher has moved past; a service's client receives a batch of requests' replies in order, owed as its sends are; a server's batches raise INVALID. Batch both ends: a receiver that takes one message per call falls behind a batching sender.
sent = conn.send_many([b"one", b"two", b"three"])

for msg in peer.recv_many(max_count=64):
    handle(msg)
Broadcast
one publisher, many subscribersA broadcast sends every message of one publisher to each of its subscribers, in any processes of the user; each message is stored once, in memory every subscriber maps. Messages are of one piece, up to a quarter of the capacity. broadcast_create returns the publisher, a Conn and the broadcast's one handle, which the with block closes; its close ends the broadcast and frees the name. The publisher's process admits each subscriber by itself, on a thread of the library's: the publisher only waits for the first one (publisher.wait_for_members(1)) before it sends tick 1 to tick 3. The subscriber joins gated (broadcast_join with SUBSCRIBER_GATED), so it misses nothing (the publisher waits for it), and receives until DISCONNECTED, which comes after the last message. A lossy subscriber (SUBSCRIBER_LOSSY) never holds the publisher back: one that falls a lap behind gets OVERRUN, and the error's lost says how many messages it lost. A gated one that holds the publisher back for the broadcast's max_stall_ms is unsubscribed (UNSUBSCRIBED).
import fipc

# 64 KiB of messages, up to 8 subscribers; one that holds the publisher back 5 s is dropped
with fipc.broadcast_create("my_broadcast", 1 << 16, 8, 5000) as publisher:
    publisher.wait_for_members(1)  # waits for the first subscriber
    for i in (1, 2, 3):
        publisher.send(f"tick {i}".encode())
# closing the publisher ends the broadcast: subscribers get DISCONNECTED after the ticksimport fipc
# gated: misses nothing (the publisher waits for it)
with fipc.broadcast_join("my_broadcast", fipc.SUBSCRIBER_GATED, timeout_ms=5000) as subscriber:
try:
while True:
print(subscriber.recv().decode()) # tick 1, tick 2, tick 3
except fipc.FipcError as e:
if e.result != fipc.Result.DISCONNECTED: # the publisher closed
raiseWork queue
many producers, each message to one consumerA work queue takes messages from up to 63 producers and hands each to one of up to 64 consumers, in any processes of the user. Each producer has a ring of its own; a consumer takes a message of any producer, and the queue promises no order. Messages are of one piece, up to a quarter of the capacity, and wait in the queue until a consumer takes them. Each message goes to one consumer, and again, to another, only if that consumer's process ends before acknowledging it (delivery, below). Here the producer creates the queue (queue_create: a Queue), joins it as its producer (queue_join with PRODUCER: the owner's process admits every joiner by itself, its own included), sends job 1 to job 3, which wait in the queue, and waits for the consumer (queue.wait_for_members(CONSUMER, 1)). The queue's close ends it: the consumer receives what is left, then DISCONNECTED, and a producer's sends raise DISCONNECTED from then on; a producer's or a consumer's close never ends the queue. A Queue never closes itself (it has no finalizer): a queue lives until close() or the end of its process, and dropping the object doesn't end it.
import fipc

# 4 KiB of messages per producer, 1 producer and 1 consumer: this process owns the queue and is its producer
with fipc.queue_create("my_queue", 4096, 1, 1) as queue:
    with fipc.queue_join("my_queue", fipc.PRODUCER) as producer:
        for i in (1, 2, 3):
            producer.send(f"job {i}".encode())  # waits in the queue until a consumer takes it
        queue.wait_for_members(fipc.CONSUMER, 1)  # waits for the consumer to join
# closing the queue ends it: the consumer gets DISCONNECTED after the jobsimport fipc
with fipc.queue_join("my_queue", fipc.CONSUMER, timeout_ms=5000) as consumer:
try:
while True:
print(consumer.recv().decode()) # job 1, job 2, job 3
except fipc.FipcError as e:
if e.result != fipc.Result.DISCONNECTED: # the queue ended
raiseDelivery. Each message goes to one consumer. It goes again, to another consumer, only if the process of the consumer that took it ends before acknowledging it, and when a consumer acknowledges is its own choice, not the queue's. A message received in place is acknowledged at its release (or the consumer's next receive, or its close).
| How the consumer receives | When it acknowledges | If its process ends | What the application gets |
|---|---|---|---|
recv() or recv_into() (copying) | inside the call, before it returns | inside the call: the message goes to another consumer, and this one never saw it; after the call returned: it doesn't go again | at most once: no duplicates |
recv_acquire(), then recv_release() at once, then the work | at the release, before the work | as above | at most once: no duplicates |
recv_acquire(), the work, then recv_release() | at the release, after the work | before the release: the message goes to another consumer | at least once: a duplicate is possible, so the work must be idempotent |
- Choose by the work, per consumer. Work that may safely run twice (rendering, a computation, re-indexing, converting a file) acknowledges after it; work whose effects must never repeat (a payment, an email, a motor command) acknowledges before it.
- Not covered: a consumer that hangs while its process runs (there are no timeouts, by design); the owner's process, with which the queue ends; a reboot. A consumer holds at most one unacknowledged message at a time, the one received in place.
- A message that goes again comes in no set order, after messages its producer sent later: the queue promises no order anyway.
- A message held in place holds back its producer's room until its release: a consumer that acknowledges after a long job keeps that message's room, and so the room of the producer's messages after it, until then.
- A message that crashes every consumer that takes it, acknowledged after the work, goes to each consumer in turn, with no limit: acknowledge before the work where that can happen.
Service
many clients, a pool of servers, with repliesA service takes requests from up to 64 clients and hands each to one of up to 64 servers, in any processes of the user; the server that took a request replies to it, and the reply goes back to the client that sent it. A server waits for the requests of every client at once (one recv), and the servers of a pool share the load: each takes the next request of any client. Each client has a ring of its own, which holds its requests and the room for their replies, so a server never waits for a client. Requests and replies are of one piece, 1 to max_message bytes, the owner's choice. Here the server creates the service (service_create: a Service), joins it as its server (service_join with SERVER: the owner's process admits every joiner by itself, its own included) and answers three requests with their uppercase. The client joins (CLIENT) and calls ping 1 to ping 3: call sends a request and returns its reply. The service's close ends it: clients' sends and servers' receives raise DISCONNECTED, and a client receives the replies that came before the end, then DISCONNECTED; a client's or a server's close never ends the service. A Service never closes itself (it has no finalizer): a service lives until close() or the end of its process, and dropping the object doesn't end it.
import fipc

# 4 KiB per client, requests and replies of up to 256 bytes, 1 client and 1 server: this process owns the service
# and is its server
with fipc.service_create("my_service", 4096, 256, 1, 1):
    with fipc.service_join("my_service", fipc.SERVER, timeout_ms=5000) as server:
        for _ in range(3):  # three requests, then the end
            request = server.recv()  # the next request of any client
            server.send(request.upper())  # the reply goes to its client, and never waits
# closing the service ends it: the client still receives the replies sentimport fipc
with fipc.service_join("my_service", fipc.CLIENT, timeout_ms=5000) as client:
for i in (1, 2, 3):
# sends the request and returns its reply; FipcError (ABANDONED) if the server ended before it replied
reply = client.call(f"ping {i}".encode())
print(reply.decode()) # PING 1, PING 2, PING 3- A client's replies come in the order of its requests.
send(request)sends a request, andrecv()(recv_into(buf), or in placerecv_acquire()untilrecv_release()) receives the reply to its oldest request whose reply it hasn't received yet, whichever server replies first. A client may send several requests before it receives (as many as its ring has room for: each holds its length rounded up to 64 bytes, plusmax_messagerounded up to 64, until its reply has been received), and the servers work on them at once. A receive that times out or is cancelled leaves its reply to come: the next receive returns it. call(request)never returns another request's reply. A call checks its request first:INVALIDfor an empty one,TOO_LARGEovermax_piece(), at once, even while a reply is owed. Then a call on a cancelled connection raisesCANCELLEDat once, whatever its timeout, and sends nothing: it could never receive the reply. The connection keeps count of the replies still owed: a call whose receive timed out or was cancelled leaves its reply owed, and the next call first receives and drops that reply (at most one is owed, since every call drops it first; anABANDONEDin its place counts too), within its own timeout and before it sends. A call that had to drop an owed reply first sends its request only if its timeout has time left: once a positive timeout has run out, it raisesTIMEOUTwithout sending, so no server sees that request; withNO_WAIT(0) no step waits, and it sends if there is room. After a call that gave up, a plainrecvreturns that call's late reply (orABANDONED) first: replies come in request order. A call raisesINVALIDwhile a request sent withsendstill has its reply to be received: that reply is yours, so receive it first. A call sends and receives, so no other thread may send or receive on the connection meanwhile.- A server holds one request at a time.
recv()takes the next request of any client (each client's in the order it sent them), andsend(reply)replies to it and never waits; until then its receives raiseINVALID, and a reply with no request held raisesINVALID. A request received in place stays valid until the reply'ssendorsend_commit;recv_release()does nothing. A reply to a client that has left is dropped. A server may receive on one thread and reply on another. Itsclose()answers the request it holdsABANDONED, and so does the garbage collection of a server'sConnleft unclosed: a server holds its request, and its client waits for the reply, until it is closed (withwithorclose()) or garbage-collected (or its process ends). ABANDONED: a client's receive (or call) raises it when the server that took the request ended before it replied: it closed its connection, or its process ended. The request counts as answered, and the next receive returns the next reply. An abandoned request may or may not have been carried out; the service never sends it again, and the client decides whether to.- The owner's service:
service.wait_for_members(role, at_least)waits until that many members of the role (CLIENT,SERVER, orNonefor both) have joined;service.cancel()makes its waits raiseCANCELLED, from any thread. Clients wait while no server is joined, and servers while no client is. - Not covered: a server that hangs while its process runs (there are no timeouts, by design: its client waits, within its own timeouts); the owner's process, with which the service ends.
Threads
cancel, join, closeOn a connection, one thread at a time sends and one thread at a time receives, and the two may run at once. cancel() works from any thread and makes every waiting call raise CANCELLED. close() needs the connection to itself, so stop a reader thread by cancelling, joining it, then closing. A Conn or a Listener left unclosed is closed when it is garbage-collected, never under a call (a thread inside one keeps it referenced); a Queue and a Service never are.
import threading
from fipc import FipcError

def reader():
    try:
        while True:
            handle(conn.recv())
    except FipcError:
        pass                      # CANCELLED or DISCONNECTED

t = threading.Thread(target=reader)
t.start()
...
conn.cancel()
t.join()
conn.close()
Reference
fipc| Call | What it does |
|---|---|
stream_create(name, capacity) | Claims the name for a stream and returns its Listener; ADDR_IN_USE if another stream, broadcast, queue or service holds it. Doesn't wait. |
listener.accept(timeout_ms) | Sets the next client's connection up on the calling thread and returns its Conn. One client at a time: close it before the next accept. NO_WAIT polls. |
listener.cancel() · close() | Cancel waiting accepts (any thread) · stop listening and free the name; accepted connections stay open. |
stream_connect(name, timeout_ms) | Connects to the stream's server on the name, waiting for it to create the stream and accept: client and server run on different threads or processes. |
broadcast_create(name, capacity, max_subscribers, max_stall_ms) | Claims the name for a broadcast and returns the publisher, a Conn whose sends go to every subscriber; its close (or its garbage collection) ends the broadcast. Doesn't wait: the publisher's process admits subscribers by itself. |
broadcast_join(name, role, timeout_ms) | Joins the broadcast on the name as SUBSCRIBER_LOSSY or SUBSCRIBER_GATED (misses nothing), waiting for the publisher to create it and admit the subscriber. It receives the messages sent from its admission on. |
publisher.wait_for_members(at_least, timeout_ms) | How many subscribers are joined, waiting until at least at_least are (0 returns at once). At TIMEOUT or CANCELLED, the error's count is the count. Any thread. |
queue_create(name, capacity, max_producers, max_consumers) | Claims the name for a work queue and returns its Queue. Doesn't wait: the owner's process admits producers and consumers by itself. No finalizer: the queue lives until close() or the end of its process. |
queue_join(name, role, timeout_ms) | Joins the work queue on the name as PRODUCER or CONSUMER (the owner's members too, from any thread), waiting for the owner to create it and admit the member. |
queue.wait_for_members(role, at_least, timeout_ms) | How many members of the role (PRODUCER, CONSUMER, or None for both) are joined, waiting until at least at_least are. At TIMEOUT, CANCELLED or DISCONNECTED, the error's count is the count. Any thread. |
queue.cancel() · close() | Cancel waiting wait_for_members calls (any thread; the queue goes on) · end the queue and free the name: producers' sends raise DISCONNECTED, consumers receive what is left, then DISCONNECTED. |
service_create(name, capacity, max_message, max_clients, max_servers) | Claims the name for a service and returns its Service: each client gets a ring of capacity bytes for its requests and their replies, each of up to max_message bytes. Doesn't wait: the owner's process admits clients and servers by itself. No finalizer: the service lives until close() or the end of its process. |
service_join(name, role, timeout_ms) | Joins the service on the name as CLIENT or SERVER (the owner's members too, from any thread), waiting for the owner to create it and admit the member. |
service.wait_for_members(role, at_least, timeout_ms) | How many members of the role (CLIENT, SERVER, or None for both) are joined, waiting until at least at_least are. At TIMEOUT, CANCELLED or DISCONNECTED, the error's count is the count. Any thread. |
service.cancel() · close() | Cancel waiting wait_for_members calls (any thread; the service goes on) · end the service and free the name: clients' sends and servers' receives raise DISCONNECTED, clients receive the replies that came before the end, then DISCONNECTED. |
client.call(request, timeout_ms) | A service's client: sends the request and returns its reply (ABANDONED if its server ended first). INVALID for an empty request, TOO_LARGE over max_piece(), at once. It first drops the reply owed to an earlier call that timed out or was cancelled, and raises TIMEOUT without sending if that took all its time; INVALID while a request of send has its reply to be received. |
conn.send(data) · recv() | Copy one message of any size in · out, as bytes. A lossy subscriber that fell a lap behind gets OVERRUN, with the number of messages lost in the error's lost. |
recv_into(buf) | Receives into your bytearray or memoryview and returns the length. |
send_many(messages) · recv_many(max_count) | Batches: send a list of messages, published together, and return how many went (on an error, its sent) · receive every message already there, up to max_count, as a list. Batch both ends. |
send_acquire(n) · send_commit(n) | Zero-copy send. |
recv_acquire() · recv_release() | Zero-copy receive. |
max_piece() · cancel() · close() | The zero-copy limit · cancel waiting calls (any thread) · end the connection (the garbage collector closes one left unclosed). |
Measured through this binding, copied 16-byte messages run at about 1.2 to 1.5 million per second, and 64 KiB messages at about 320,000 to 340,000 per second (details).